
I thought it was a bad sign at the end of 2008 and first half of 2009 when practically every new service or application that came my way was simply an extension to or enhancement of other already-popular social networks, almost always for Twitter, Facebook or FriendFeed. Even then, the cacophony of noise around Twitter practically drowned out all of it. Amid an unrelenting flurry of Twitter clients for desktop and Web and Twitter tools for unfollowing, grouping, analyzing and reporting, we also had a rush of Twitter-related sites, all aiming to find their own special niche. Among the most successful, after a slow start, was TweetMeme, the brainchild of Fav.or.it founder Nick Halstead, who managed to repurpose the company and ride the wave of Twitter and retweeting at the perfect time. Seeing his success, a new challenger with a killer domain name (ReTweet.com) is looking to unseat him, by essentially doing the same thing - tabulating the most popular shared items on Twitter.
Scratch that. They're doing the exact same thing, and the complete copycat style is insulting to anybody who deigned to take them seriously. While I had seen complaints about copyright infringement and code borrowing, I had no idea how terrible the attempt had been until tonight, when it became crystal clear how much ReTweet.com stole from TweetMeme before hitting the publish button.
On first glance, both sites display what you would expect - popular articles from often retweeted sites like Mashable.com and the comic XKCD.com. Popular post titles have very similar numerical scores, as you would also expect - varying as little as just over 1 percent on articles that have more than 1,000 retweets. And yes, both let you dice and slice the data by one day or seven (although ReTweet.com calls it one week instead of 7 days and TweetMeme.com calls it 24 hours instead of 1 day. You get it...).
I've seen Digg and I've seen Digg clones. I've seen popular aggregators and their clones. I've seen social networks and their clones. And I recognize that sites that serve similar functions are yes, going to look similar. But once you move past the similar front page, the blatant stealing is jaw-dropping.
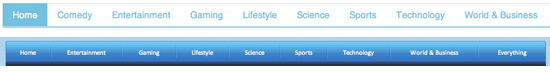
TweetMeme has a top level navigation bar, which read from left to right, says:
- Home
- Comedy
- Entertainment
- Gaming
- Lifestyle
- Science
- Sports
- Technology
- World&Business
- Home
- Entertainment
- Gaming
- Lifestyle
- Science
- Sports
- Technology
- World&Business
- Everything
I don't even want to begin to understand why people think this is okay. While Nick and I once disagreed about his first product's direction and how well that beta was prepared, I never questioned his company's trying to do something different in a competitive landscape. But what ReTweet.com is doing is upsetting. While a service like TweetMeme.com was practically inevitable, and competition is healthy, this kind of stealing and underhanded non-innovation is troubling. If this is what is acceptable from engineering teams these days, then innovative services have got to be worried about protecting their intellectual property.
When, at last month's Lunch 2.0 panel, I asked Bret Taylor of FriendFeed how he felt about services like Facebook and Google Reader borrowing aspects of FriendFeed, such as the "Like" feature, he said he felt "good" because he was making an impact on the Web and it showed alignment between differing Web properties, adding he didn't feel the company could patent words on a Web page. But I am sure the level of copycat dunderheadery on the part of ReTweet.com is not something any of us should "feel good" about. If you want to compete in this space, and you want to take on a market leader, you have got to make sure you offer real differentiation based on different source data, different splicing, different display or different intent. This attempt is a sorry gimmick that has got to have the TweetMeme.com team seeing red, and rightly so.
I'm done linking to ReTweet.com now. The next time I want to be writing about them is if they get sued or when they close down. Not impressed. This kind of launch is bad for innovation and bad for the Web.
 At one time, I thought

 There's no question that some of the most popular Web ventures are centered around finding that perfect someone, or at least centered around looking at perfect pictures. The popular
 In late August,
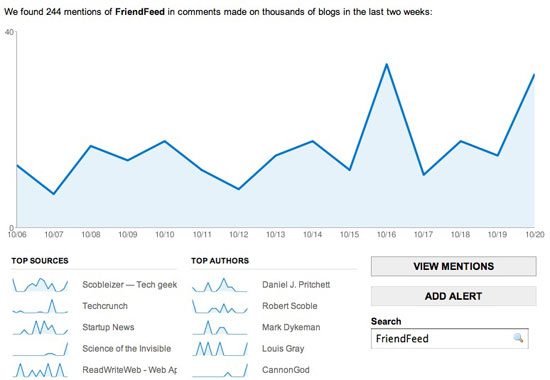
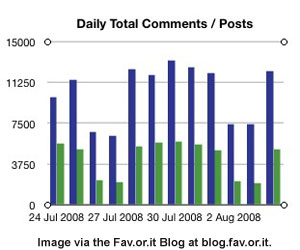 An initial post by Nick Halstead, titled "
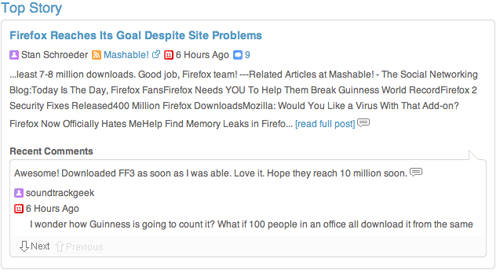
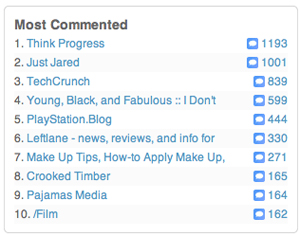 Duncan Riley of the Inquisitr
 What Fav.or.it does do well is deliver a clean-looking site, with a strong amount of underlying data, easily findable. There's clearly a robust underlying database of stories and metadata around tags and comments powering the site, but it does a much better job than other sites, like
 Talking about Fav.or.it now, as TechCrunch has with their piece,
 Today's news on
 Friday night's discussion around the fragmenting of comments between blogs,
 I first became excited about Fav.or.it's potential to compete with

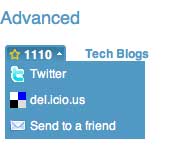 But while that's nice, and noble, it certainly couldn't overcome the interface oddities I seemingly encountered at every turn. My slice "Tech Blogs" was marked with a number of 1110, with no seeming rhyme or reason, and clicking the 1110 showed Twitter, del.icio.us or send to a friend, without any indication of what clicking those items would do. Clicking the first two items gave me a checkmark, but no action.
 On March 3rd of last year, I posted one of the more active and popular posts in louisgray.com's history, offering my thoughts on